Qwen3.8 Flash Next GGUF Benchmark: Q4 to Q1 Accuracy and Token Efficiency kaitchup.substack.com
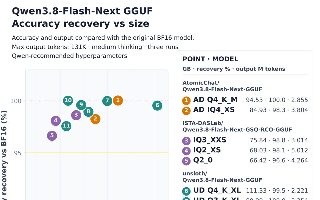
Benjamin Marie benchmarked 12 quantized GGUF versions of Qwen3.8 Flash Next against the 354 GB BF16 model, measuring accuracy and token efficiency across 42.7 million generated tokens. All 11 standard quantizations—from Q4 to Q1—retained at least 95% of the reference model’s accuracy; a separate pruned-and-quantized Coder release preserved coding performance but lost ground in general knowledge and scientific reasoning.